Showing posts with label numpy. Show all posts

Friday, 9 February 2024

Exact reproducibility of stochastic simulations for parallel and serial algorithms simultaneously
Random Stream Chunking

Preamble 

Figure: Visual description of
random stream chunking, M.Suzen (2017)
The advent of using computational sciences approaches, i.e., data science and machine learning, in the industry becomes more common practice in almost all organisations due to the democratisation of data science tools and availability of inexpensive cloud infrastructure. This brings the requirement or even compulsory practice of a code being so called parallelised. Note that parallelisation is used as an umbrella term here for using multiple compute resources in accelerating otherwise a serial computation and could mean a distributed or multi-core computing, i.e., multiple CPUs/GPUs. Here we provide a simple yet a very powerful approach to preserve reproducibility of parallel and serial implementation of the same algorithm that uses random numbers, i.e., stochastic simulations. We assume Single Instruction Multiple Data (SIMD) setting. 

Terminology on repeatability, reproducibility and  replicability 

Even though we only use reproducibility as a term as an umbrella term, there are clear distinctions, recommended by ACM, here. We summarise this from computational science perspective :

repeatability : Owner re-run the code to produce the same results on own environment. 
reproducibility: Others can  re-run the code to produce the same results on other's environment. 
replicability: Others can re-code the same thing differently and produce the same results on other's environment. 

In the context of this post, since parallel and serial settings would constitute different environments, the practice of getting the same results, this falls under reproducibility.   

Single Instruction Multiple Data (SIMD) setting. 

This is the most used, and probably the only one you would ever need, approach in parallel processing. It implies using the same instruction, i.e., algorithm or function/module, for the distinct portions of the data. This originates from applied mathematics techniques so called domain decomposition method. 

Simultaneous Random Stream Chunking 

The approach in ensuring exact reproducibility of a stochastic algorithm in both serial and parallel implementation lies in default chunking in producing the random numbers both in serial and parallel code. This approach used in the Bristol Python package Here is the mathematical definition. 

Defintion Random Stream Chunking Given a random number generator $\mathscr{R}(s_{k})$ with as seed $s_{k}$ is used over $k$-partitions. These partitions are always corresponds to $k$ datasets, MD portion of SIMD. In the case of parallel algorithms, each $k$ corresponds to a different compute resource     $\mathscr{C}_{k}$. 

By this definition we ensure that both parallel and serial processing receiving exactly the same random number, this is summarised in the Figure.

Conclusion

We outline a simple yet effective way of ensuring exact reproducibility of serial and parallel simulations simultaneously. However, reproducibility of stochastic simulations are highly hardware dependent as well, such as GPUs and NPUs, and their internal streams might not be that easy to control partitions, but generic idea presented here should be applicable.


Please cite this article as: 

 @misc{suezen24rep, 
     title = {Exact reproducibility of stochastic simulations for parallel and serial algorithms simultaneously}, 
     howpublished = {\url{https://memosisland.blogspot.com/2024/02/exact-reproducibility-of-stochastic.html}, 
     author = {Mehmet Süzen},
     year = {2024}
}


Tuesday, 12 May 2020

Collaborative data science: High level guidance for ethical scientific peer reviews

Preamble


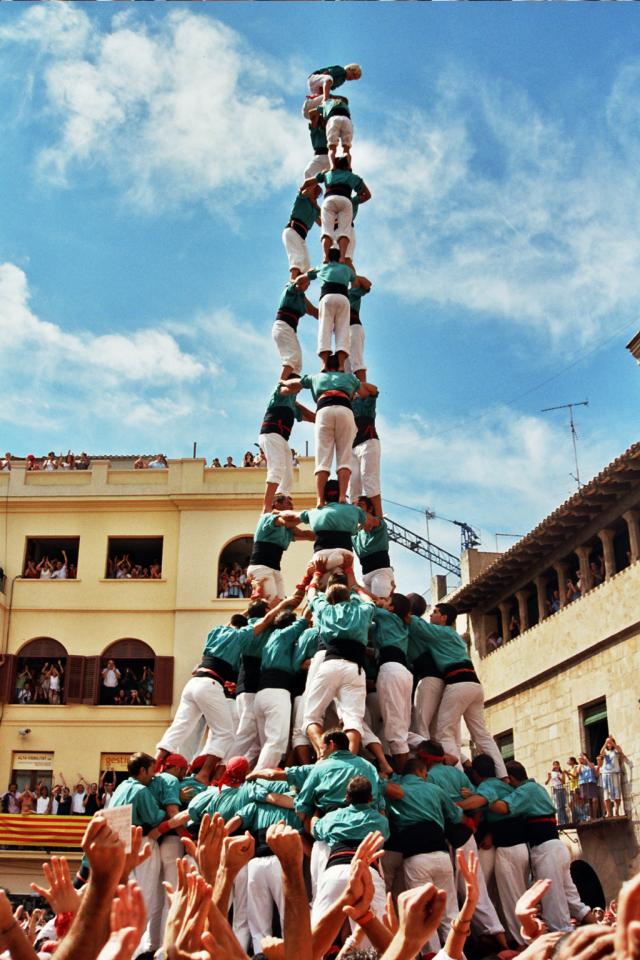
Catalan Castellers are
collaborating (Wikipedia)
Availability of distributed code tracking tools and associated collaborative tools make life much easier in building collaborative scientific tools and products. This is now especially much more important in data science as it is applied in many different industries as a de-facto standard. Essentially a computational science field in academics now become industry-wide practice.

Peer-review is a pull request


Peer-reviews usually appears as pull requests, this usually entails a change to base work that achieves the certain goal by changes. A nice coincidence that acronym PR here corresponds to both peer review and pull request.


Technical excellence does come with decent behaviour


Aiming at technical excellence is all we need to practice. Requesting technical excellence in PRs is our duty as peers. However, it does come with a decent behaviour. PRs are tools for collaborative work, even if it isn't your project or you are in a different cross-function. Here we summarise some of the high-level points for PRs. This can manifest as software code, algorithmic method or a scientific or technical article:
  • Don’t be a jerk  We should not request things that we do not practice ourselves or invent new standards on the fly.   If we do, then give a hand in implementing it.
  • Focus on the scope and be considerate We should not request things that extend the scope of the task much further than the originally stated scope.   
  • Nitpicking is not attention to details Attention to details is quite valuable but excessive nitpicking is not.
  • Be objective and don’t seek revenge If someone of your recommendations on PRs is not accepted by other colleague don’t seek revenge on his suggestions on your PRs by declining her/his suggestions as an act of revenge or create hostility towards that person.

Conclusion


We provided some basic suggestion on high-level guidance on peer review processes. Life is funny, there is a saying in Cyprus and probably in Texas too, -what you seed you will harvest-..

Wednesday, 3 April 2013

Reading Binary Data Files Written in C: Python - Numpy Case Study

One of the major components of  scientific computation is producing results into a file. Usually bunch of numbers, usually structured, is written into so called data files. Writing  binary files as outputs is practised commonly. It is the choice due to good speed and/or memory efficiency compare to plain ASCII files. However, a care on documenting  endianness must be observed for good portability.

There are many popular languages to achieve the above task. For speed and efficiency reasons usually C or Fortran is used in writing out a binary file. Let's give an example of writing one integer (42) and three doubles (0.01, 1.01, 2.01) into binary file in C:

 1
 2
 3
 4
 5
 6
 7
 8
 9
10
11
12
13
14
15
16
17
18
19
20
#include <stdio.h>
#include <stdlin.h>

int main() {
  FILE * myF;
  int i,j;
  double *numbers, kk;

  myF     = fopen("my.bindata", "wb") ;
  numbers = malloc(3*sizeof(double));
  i = 42;
  fwrite(&amp;i, sizeof(int), 1, myF);
  for(j=0; j<3; j++) {
    kk = (double)j+1e-2;
    numbers[j] = kk;
  }
  fwrite(numbers, sizeof(double), 3, myF);
  fclose(myF);
  return(0);
}

This code would produce a binary file called my.bindata. Our aim is to read this into Python so we can post-process the results i.e. visualisation or further data analysis. The core idea is to use higher language in processing the outputs directly instead of writing further C code; so to speak avoiding one more step in our work flow and avoiding cumbersome compilation of extra C code.

In order to read from files byte by byte, the standard library of Python provides a module called struct. Basically this module provides packing and unpacking of data into or from binary sources, in this case study our source is a file. However it is tedious and error prone to use this in a custom binary file where format would contain different types. Well at least needs an effort to read our custom binary file. At this point, our friend is Numpy facilities. Specially two functionality;
numpy.dtype and numpy.fromfile. The former provides an easy way of defining our file's format similar to Fortran syntax via creation of a data type object as its name stands. The later is a direct way of reading the binary file in one go that would return us a Python object that contains the all information present in the data file.
Here is the Numpy code that reads our binary file created by the above C code.

 1
 2
 3
 4
 5
 6
 7
 8
 9
10
11
import numpy as np
dt      = np.dtype("i4, (3)f8")
myArray = np.fromfile('my.bindata', dtype=dt)
myArray[0] 
#(42, [0.01, 1.01, 2.01])
myArray[0][1] 
#array([ 0.01,  1.01,  2.01])
myArray[0][0] 
#42
myArray[0][1][1] 
#1.01
 
I have tested this case study on GNU/Linux PC, so the binary file is little-endian hence the writing and reading patterns.  Ideally a generic wrapper around this Python code would help to simplify things.
(c) Copyright 2008-2024 Mehmet Suzen (suzen at acm dot org)

Creative Commons License
This work is licensed under a Creative Commons Attribution 4.0 International License