Showing posts with label machine learning. Show all posts

Tuesday, 22 April 2025

Numerical stability showcase: Ranking with SoftMax or Boltzmann factor

Preamble 

Image: Babylonian table for
computation (Wikipedia)
Probably, one of the most important aspects of computational work in quantitative fields, such as physics and data sciences is stability of numerical computations. It implies given inputs, outputs should not wildly deviates to large numbers or it must not distort the results, such as ranking based on scores, one of the most used computation in data science tasks, such as in classification of clustering. In this short post, we provide a stunning example of using SoftMax that creates wrong results if it applied naively. 

SoftMax:  Normalisation with Boltzmann factor

SoftMax is actually something more physics concept than a data science usage. The most common usage in data science is used for ranking.  Given a vector $x_{i}$, then softmax can be computed with the following expression read $$exp(x_{i})/\sum_{i} exp(x_{I}).$$ This originates from statistical physics, i.e., Boltzmann factor. 

Source of Numerical Instability

Using exponential function in the denominator in a sum creates a numerical instability, if one of the number deviates from other numbers significantly in the vector. This makes all other entries zero for the output of softmax.  

Example Instability: Ranking with SoftMax

Let's say we have the following scores 

scores = [1.4, 1.5, 1.6, 170]

for teams A, B, C,  D for some metric, we want to turn this into probabilistic interpretation with SoftMax, this will read, [0., 0., 0., 1.] we see that D comes on top but A,B,C are tied. 

LogSoftMax

We can rectify this instability by using LogSoftMax. reads $$\log exp(x_{I})-log(\sum_{i} exp(x_{i})),$$reads [-168.6000, -168.5000, -168.4000, 0.0000], so that we can induce consecutive ranking without ties, as follows D, A, B, C.

Conclusion

There is a similar practice in statistics for likelihood computations, as Gaussians brings exponential repeatedly. Using Log of the given operations will stabilise the numerical instabilities caused by repeated exponentiation. This shows the importance of numerical pitfalls in data sciences. 

Cite as follows

 @misc{suezen25softmax, 
     title = {Numerical stability showcase: Ranking with SoftMax or Boltzmann factor}, 
     howpublished = {\url{https://memosisland.blogspot.com/2025/04/softmax-numerical-stability.html}}, 
     author = {Mehmet Süzen},
     year = {2025}
}  

Appendix: Python method 

A python method using PyTorch computing softmax example from the main text. 

import torch

List = list
Tensor = torch.tensor

def get_softmax(scores:List, log :bool = False) -> Tensor:
"""
Compute softmax of a list

Defaults to LogSoftMax
"""
scores = torch.tensor(scores)
if log:
scores = torch.log_softmax(scores, dim=0)
else:
scores = torch.softmax(scores, dim=0)
return scores


Saturday, 28 September 2024

Matrix language conjecture for combinatorics:
Combinatorial set generation via nested cartesian products

Rubik's cube (Wikipedia)

Preamble
 

Counting is one of the most important concepts in probability and statistical mechanics as well. Two primary characteristics of choosing $n$ items from $N$ items are (no)-order and (no)-repeat. This leads to four  possible cases that leads to combinations and permutations of different kinds to found the resulting set size. Specially the case for repeated no-ordering would be quite hard to memorise or derive on the spot. There is a catch, we can compute the set sizes in combinatorics but usually there is no explicit explanation how could we get the entire combinatorial set member via a computation.  In this short exposition, we have demonstrated a conjecture  that obtaining resulting combinatorial set members is possible via nested cartesian products of the set of the $N$ items: Concepts from matrices help to identify resulting set members in the given combinatorics case.  

Compact Combinatorics

Combinatorics over choosing $n$ items over $N$ has four cases as mentioned. Here is the formulations of choosing sets over $N$ items of size $n$ with different constraints, resulting set sizes will be: 

  • Ordering matters with replacement : $N^n$
  • Ordering matters without replacement: $\Large \frac{N!}{(N-n)!} $
  • Ordering doesn't matter with replacement: $\Large \frac{(n+N-1)!}{n!(N-1)!}$
  • Ordering doesn't matter without replacement: $\Large \frac{N!}{n!(N-n)!} $
However, it is often we forget the formulations of the each case, even to identify the case given a problem.

Obtaining resulting sets: Combinatorial Matrix

We know the size of the resulting sets if we do the choose over a set given $n$. However, the members of the resulting set is not usually known via a computational procedure in standard texts. However, this is possible via cartesian product of the initial set by itself if $n=2$, i.e., pairwise matrices over $N$ item, a combinatorial matrix.     

Matrix language conjecture for combinatorics: A combinatorial matrix has different portions. An entire matrix (E), diagonals (D), upper diagonal (UD) and lower diagonal (LD).  These portions or combinations of them corresponds to the cases above, somehow obvious after a close look: 

  • Ordering matters with replacement : E
  • Ordering matters without replacement: E-D
  • Ordering doesn't matter with replacement:   UD+D or LD+D   
  • Ordering doesn't matter without replacement: UD or LD
By choosing certain portions of the matrix we full-fill constraints of generating new sets. 

Nested Combinatorial Matrices ($n \ge 3$  cases) 

It is obvious that the above conjecture is valid for $n=2$. In the case of where $n \ge 3$ we would need to do more cartesian products over a combinatorial matrix selectively. The idea is as follows: we generate new cartesian products with $N$ items row-wise with removal of the base row at each level due to portions selected. Here is the sketch of the nested cartesian products: 

  1. We start with the case of $n=2$ and generate the matrix.  Retain the corresponding matrix portion.
  2. Then repeat portion for the next levels till exhaustion that items are size $n$: We do cartesian product of the given row to all items again to generate new combinatorial matrix of each element, except the elements deleted from the row due to portion selection, if deleted.
  3. At the end we obtain multiple matrices of possibly different sizes, then choose the portions again to form the resulting set of combinatorial items. 

Conclusion

We have discussed shortly how to leverage a matrix language in finding the resulting sets in core combinatorics counting operations. This could be used as a pedagogical tool, algorithmic development and bringing new relationships between matrices and combinatorial formula. This is still a conjecture, but taught provoking one that connects matrix generation to combinatorial structures.  

Cite this as follows: 

 @misc{suezen24mcg, 
     title = { Matrix language conjecture for combinatorics: Combinatorial set generation via nested cartesian products}, 
     howpublished = {\url{https://memosisland.blogspot.com/2024/09/combinatorics-touch-of-linear-algebra.html}}, 
     author = {Mehmet Süzen},
     year = {2024}
}  


Saturday, 1 June 2024

A new kind of AutoML: On the fallacy of many-shot in-context learning with LLMs and PLMs

Extension of this post, appear as a short article with a conjecture:

Preamble 

With the common usage of  Pre-trained Large  Language Models (PLMs/LLMs), now it is possible to direct them to make data analysis, generate predictions or code for very specialised tasks without training. The primary approach in doing such automated analysis is using many-shot learning. In this short post, it is pointed out that pushing analysis into meta model doesn't remove the analyst, as there are now some claims doing so. This is a common generalisation fallacy in many AI systems. Humans are actually are still in the loop and certain automation presented as if human's are removed entirely is not a fair representation of the capabilities and advantages brought by these models. 

How to direct PLMs to do new-prediction without training?

Graph Path (Wikipedia)

This is quite an attractive premise. Using a foundational model, we could update their ability of prediction beyond training data by simply inducing a memory in their input, so called Chain-of-Though (CoT). At this point, we can deploy the model for an automated task with invoking CoT before its first prompt. This is a new kind of AutoML approach, that supervised learning takes a new great-look: pushes training efforts to building chain-of-thought datasets. Building CoTs appears to be a meta modelling tasks and requires domain knowledge to develop.

Did we really remove the data analyst, software developer or the practitioner from the loop? 

Short answer is No. What we did by is a new way of performing a specialised task, i.e., modelling is moved into a meta modelling stage. Meaning a memory induced by CoT is  designed by experienced human and it will be broken if the task or input data deviates a little differently. A usual culprit in play here; a reliability is problematic. Even though this is quite a promising development and potential to be a game changer on how we practice machine learning, error-rates are still quite high, see Agarwal-Singh et. al. (2024).  

Conclusion 

In this short exposition, we argue that many-shot learning, chain-of-thought learning for foundation models is actually a new kind of AutoML tool. AutoML doesn't imply that human expert is removed from the picture completely. However it greatly assist the scientist, analyst, programmer or practitioner, in automating some tasks as meta programming tool. It will also help less-experienced colleague to start being a bit more productive. These tools indeed improves our computational tool boxes, specifically as a new AutoML tool.  

Further reading

Please cite as follows:

 @misc{suezen24pmlauto, 
     title = {A new kind of AutoML: On the fallacy of many-shot in-context learning with LLMs and PLMs}, 
     howpublished = {\url{https://memosisland.blogspot.com/2024/05/llm-analysis-fallacy.html}, 
     author = {Mehmet Süzen},
     year = {2024}
}  

Friday, 9 February 2024

Exact reproducibility of stochastic simulations for parallel and serial algorithms simultaneously
Random Stream Chunking

Preamble 

Figure: Visual description of
random stream chunking, M.Suzen (2017)
The advent of using computational sciences approaches, i.e., data science and machine learning, in the industry becomes more common practice in almost all organisations due to the democratisation of data science tools and availability of inexpensive cloud infrastructure. This brings the requirement or even compulsory practice of a code being so called parallelised. Note that parallelisation is used as an umbrella term here for using multiple compute resources in accelerating otherwise a serial computation and could mean a distributed or multi-core computing, i.e., multiple CPUs/GPUs. Here we provide a simple yet a very powerful approach to preserve reproducibility of parallel and serial implementation of the same algorithm that uses random numbers, i.e., stochastic simulations. We assume Single Instruction Multiple Data (SIMD) setting. 

Terminology on repeatability, reproducibility and  replicability 

Even though we only use reproducibility as a term as an umbrella term, there are clear distinctions, recommended by ACM, here. We summarise this from computational science perspective :

repeatability : Owner re-run the code to produce the same results on own environment. 
reproducibility: Others can  re-run the code to produce the same results on other's environment. 
replicability: Others can re-code the same thing differently and produce the same results on other's environment. 

In the context of this post, since parallel and serial settings would constitute different environments, the practice of getting the same results, this falls under reproducibility.   

Single Instruction Multiple Data (SIMD) setting. 

This is the most used, and probably the only one you would ever need, approach in parallel processing. It implies using the same instruction, i.e., algorithm or function/module, for the distinct portions of the data. This originates from applied mathematics techniques so called domain decomposition method. 

Simultaneous Random Stream Chunking 

The approach in ensuring exact reproducibility of a stochastic algorithm in both serial and parallel implementation lies in default chunking in producing the random numbers both in serial and parallel code. This approach used in the Bristol Python package Here is the mathematical definition. 

Defintion Random Stream Chunking Given a random number generator $\mathscr{R}(s_{k})$ with as seed $s_{k}$ is used over $k$-partitions. These partitions are always corresponds to $k$ datasets, MD portion of SIMD. In the case of parallel algorithms, each $k$ corresponds to a different compute resource     $\mathscr{C}_{k}$. 

By this definition we ensure that both parallel and serial processing receiving exactly the same random number, this is summarised in the Figure.

Conclusion

We outline a simple yet effective way of ensuring exact reproducibility of serial and parallel simulations simultaneously. However, reproducibility of stochastic simulations are highly hardware dependent as well, such as GPUs and NPUs, and their internal streams might not be that easy to control partitions, but generic idea presented here should be applicable.


Please cite this article as: 

 @misc{suezen24rep, 
     title = {Exact reproducibility of stochastic simulations for parallel and serial algorithms simultaneously}, 
     howpublished = {\url{https://memosisland.blogspot.com/2024/02/exact-reproducibility-of-stochastic.html}, 
     author = {Mehmet Süzen},
     year = {2024}
}


Tuesday, 22 June 2021

Full cross-validation and generating learning curves for time-series models

Kindly reposted to KDnuggets by Gregory Piatetsky-Shapiro

Preamble

Time-series analysis is needed almost in any quantitative field and real-life systems that collects data over time, i.e., temporal datasets. Building predictive models on temporal datasets for future evolution of systems in consideration are usually called forecasting. The validation of such models deviates from the standard holdout method of having random disjoint splits of train, test and validation sets used in supervised learning. This stems from the fact that time-series are ordered and order induces all sorts of statistical properties that should be retained. For this reason, applying direct cross-validation to time-series model building is not possible and only restricted to out-of-sample (OOS) validation, using the end-tail of a temporal set as a single test set. A recent work proposed an approach that overcomes the known limitation achieving full cross-validation for time-series. The approach opens up for a possibility to produce learning curves for the time-series models as well, which is usually also not possible due to similar reasons.

Reconstructive Cross-validation (rCV) : A meta-algorithm design principles

rCV is proposed recently in the paper titled Generalised learning of time-series: Ornstein-Uhlenbeck processes. The design principles of rCV for time-series aims at the following principles:

   Figure 1 : rCV meta-algorithm for time-series
cross-validation and learning curves.

  1. Logically close to standard cross-validation: Arbitrary test-set size and number of folds. 
  2. Preserve correlations and data order. 
  3. Does not create absurdity of predicting past from the future data. 
  4. Applicable in generic fashion regardless of learning algorithm. 
  5. Applicable to multi-dimensional time-series. 
  6. Evaluation metric agnostic.

Idea of introducing missing-data  : Temporal cross-validation and learning curves

The key idea of rCV is to create cross-validation sets via creating missing-data sets K-times, as in K-fold, with a given degree of missing ratio, i.e., random data point removal. Each fold will have disjoint set of missing data points. By an imputation method, we would fill out the K-disjoint missing data sets and generate K-different training datasets.  This would allow us to have K-different models and we could measure the generalised performance of the modelling approach by testing the primary models prediction on the Out-of-sample (OOS) test set. To avoid confusion about what is a model?, what we are trying to achieve is to find out hypothesis, i.e., the modelling approach.  By changing the ratio of missing data and repeating the cross-validation exercise will yield to set of ratio of missing-missing data introduced and their corresponding rCV errors, the plot is nothing but a learning-curve from supervised learning perspective.  Note that the imputation and prediction models are different models. The primary model we are trying to build is the prediction model we used for producing OOS predictions. The procedure is summarised in Figure 1. 


    Figure 2 : Synthetic data and reconstructions. 


Show-case with Gaussian process models on Ornstein-Uhlenbeck processes


To demonstrate the utility of rCV, the mentioned paper uses a synthetic data generated by Ornstein-Uhlenbeck process, i.e., Gaussian process with certain parameter setting.  Figure 2, shows the synthetic data and example locations of generated missing-data sets's reconstruction errors. Figure 3 shows learning curves depending on the different ratios of missing data setting. 

    Figure 3: Learning curves for the Gaussian Process model
generated by rCV.


Conclusion

rCV provides logically consistent way of practicing cross-validation in time-series. It is usually not possible to produce learning-curves on the same time-window for time-series model: by using rCV with different ratio missing data achieves this as well. rCV paves way to do generalised learning for time-series.

Further Reading

Apart from the paper Generalised learning of time-series: Ornstein-Uhlenbeck processes. the results can be reproduced with the Python prototype implementation,  here.

Tuesday, 29 December 2020

Practice causal inference: Conventional supervised learning can't do inference

Domino OR-gate (Wikipedia)
Preamble

A trained model may provide predictions about input values it may never seen before but it isn't an inference, at least for 'classical' supervised learning. In reality it provides an interpolation from the training-set, i.e., via function approximation: 

Interpolation doesn't mean to have all predictions within  convex-hull of the training set but interpolation as in numerical procedure of using training data only.

What does inference means? 

By inference, "we imply going beyond training data", reference to distributional shift, compositional learning or similar type of learning, should have been raised. This is specially apparent, for example, a human infant may learn  how 3 is similar to 8, but without labels supervised learning in naïve setting can't establish this, i.e., MNIST set without 8 can not learn what is 8 in plain form.

In the case of ontology inference, ontology being a causal graph, that is a "real" inference as it symbolically traverse a graph of causal connections. 

Outlook

We might be able to directly transfer that to regression scenario but probably it is possible with altering our models with SCMs and hybrid symbolic-regression approach. 

Postscript
  • Looper repo provides a resource list for causal inference looper 
  • Thanks to Patrick McCrae for invoking ontology inference comparison.
Cite

 @misc{suezen20pci, 
     title = {Practice causal inference: Conventional supervised learning can't do inference}, 
     howpublished = {\url{https://memosisland.blogspot.com/2020/12/practice-causal-inference-conventional.html}, 
     author = {Mehmet Süzen},
     year = {2020}
}
  

Sunday, 1 November 2020

Gems of data science: 1, 2, infinity

 Summary

Figure: George Gamow's book. (Wikipedia)
Problem-solving is the core activity of data science using scientific principles and evidence. On our side, there is an irresistible urge to solve the most generic form of the problem. We do this almost always from programming to formulation of the problem. But, don't try to solve a generalised version of the problem. Solve it for N=1 if N is 1 in your setting, not for any integer: Save time and resources and try to embed this culture to your teams and management. Extent later when needed on demand.

Solving for N=1 is sufficient if it is the setting


This generalisation phenomenon manifests itself as an algorithmic design: From programming to problem formulation, strategy and policy setting. The core idea can be expressed as mapping, let's say the solution to a problem  is a function, mapping from one domain to a range 

$$ f : \mathbb{R} \to \mathbb{R} $$

Trying to solve for the most generic setting of the problem, namely multivariate setting

$$ f : \mathbb{R}^{m} \to \mathbb{R}^{n} $$

where $m, n$ are the integers generalising the problem.  

Conclusion

It is elegant to solve a generic version of a problem. But is it really needed? Does it reflect reality and would be used? If N=1 is sufficient, then try to implement that solution first before generalising the problem. An exception to this basic pattern would be if you don't have a solution at N=1 but once you move larger N that there is a solution: you might think this is absurd, but SVM works exactly in this setting by solving classification problem for disconnected regions.

Postscripts

  • The title intentionally omits three, while it is a reference to Physics's inability to solve, or rather a mathematical issue of the three-body problem.


Sunday, 28 June 2020

Conjugacy and Equivalence for Deep Neural Networks: Architecture compression to selection

Preamble


A recently shown phenomenon can classify deep learning architectures with only using the knowledge gained by trained weights [suezen20a]. The classification produces a measure of equivalence between two trained neural network and astonishingly captures a family of closely related architectures as equivalent within a given accuracy. In this post, we will look into this from a conceptual perspective. 


Figure 1: VGG architecture spectral difference in the long
positive tail [suezen20a]. 
The concept of conjugate matrix ensembles and equivalence


Conjugacy is a mathematical construct reflecting different approaches to the same system should yield to the same outcome: It is reflected in the statistical mechanic's concept of ensembles. However, for matrix ensembles, like the ones offered in Random Matrix Theory, the conjugacy is not well defined in the literature. One possible resolution is to look at the cumulative spectral difference between two ensembles in the long positive tail part of the spectrum [suezen20a]. If this is vanishing we can say that two matrix ensembles are conjugate to each other. We observe this with matrix ensembles VGG vs. circular ensembles. 


 Conjugacy is the first step in building equivalence among different architectures.  If two architectures are conjugate to the same third matrix ensemble and their fluctuations on the spectral difference are very close over the spectral locations, they are equivalant in a given accuracy [suezen20a].


Outlook: Where to use equivalence in practice?

The equivalence can be used in selecting or compressing an architecture or classify different neural network architectures. Python notebook to demonstrate this with different vision architecture in PyTorch is provided, here.

Reference


[suezen20a] Equivalence in Deep Neural Networks via Conjugate Matrix Ensembles, Mehmet Suezen, arXiv:2006.13687 (2020)


Tuesday, 12 May 2020

Collaborative data science: High level guidance for ethical scientific peer reviews

Preamble


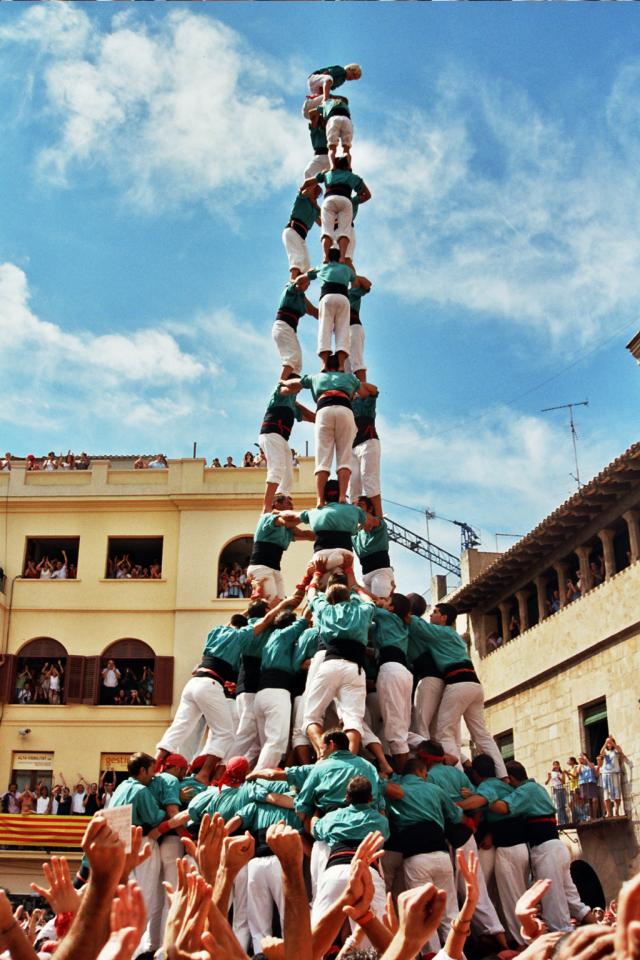
Catalan Castellers are
collaborating (Wikipedia)
Availability of distributed code tracking tools and associated collaborative tools make life much easier in building collaborative scientific tools and products. This is now especially much more important in data science as it is applied in many different industries as a de-facto standard. Essentially a computational science field in academics now become industry-wide practice.

Peer-review is a pull request


Peer-reviews usually appears as pull requests, this usually entails a change to base work that achieves the certain goal by changes. A nice coincidence that acronym PR here corresponds to both peer review and pull request.


Technical excellence does come with decent behaviour


Aiming at technical excellence is all we need to practice. Requesting technical excellence in PRs is our duty as peers. However, it does come with a decent behaviour. PRs are tools for collaborative work, even if it isn't your project or you are in a different cross-function. Here we summarise some of the high-level points for PRs. This can manifest as software code, algorithmic method or a scientific or technical article:
  • Don’t be a jerk  We should not request things that we do not practice ourselves or invent new standards on the fly.   If we do, then give a hand in implementing it.
  • Focus on the scope and be considerate We should not request things that extend the scope of the task much further than the originally stated scope.   
  • Nitpicking is not attention to details Attention to details is quite valuable but excessive nitpicking is not.
  • Be objective and don’t seek revenge If someone of your recommendations on PRs is not accepted by other colleague don’t seek revenge on his suggestions on your PRs by declining her/his suggestions as an act of revenge or create hostility towards that person.

Conclusion


We provided some basic suggestion on high-level guidance on peer review processes. Life is funny, there is a saying in Cyprus and probably in Texas too, -what you seed you will harvest-..

Saturday, 28 March 2020

Book review: A tutorial introduction to the mathematics of deep learning

Preamble
Artificial Intelligence Engines:
An introduction to the Mathematics
of Deep Learning
by Dr James V. Stone
the book and Github repository.
(c) 2019 Sebtel Press
Deep learning and associated connectionist approaches are now applied routinely in industry and academic research from image analysis to natural language processing and areas as cool as reinforcement learning. As practitioners, we use these techniques and utilise them from well designed and tested reliable libraries like Tensorflow or Pytorch as shipped black-boxed algorithms. However, most practitioners lack mathematical foundational knowledge and core algorithmic understanding. Unfortunately, many academic books and papers try to make an impression of superiority show subliminally and avoid a simple pedagogical approach. In this post we review, a unique book trying to fill this gap with a pedagogical approach to the mathematics of deep learning avoiding showing of mathematical complexity but aiming at conveying the understanding of how things work from the ground up. Moreover, the book provides pseudo-codes that one can be used to implement things from scratch along with a supporting implementation in Github repo. Author Dr James V. Stone, a trained cognitive scientist and researcher in mathematical neuroscience provides such approaches with other books many years now, writing for students, not for his peers to show off. One important note that this is not a cookbook or practice tutorial but an upper-intermediate level academic book.

Building associations and classify with a network

The logical and conceptual separation of associations and classification tasks are introduced in the initial chapters. It is ideal to start with from learning one association with one connection to many via gentle introduction to Gradient descent in learning the weights before going to 2 associations and 2 connections. This reminds me of George Gamow's term 1, 2 and infinity as a pedagogical principle. Perceptron is introduced later on how classification rules can be generated via a network and the problems it encounters with XOR problem.

Backpropagation, Hopfield networks and Boltzmann machines

Detail implementation of backpropagation is provided from scratch without too many cluttering index notation in such clarity. Probably this is the best explanation I have ever encountered. Following chapters introduced Hopfield networks and Boltzmann machines from the ground up to applied level. Unfortunately, many modern deep learning books skip these two great models but Dr Stone makes these two models implementable for a practitioner by reading his chapters.  It is very impressive. Even though I am a bit biased in Hopfield networks as I see them as an extension to Ising models and its stochastic counterparts, but I have not seen anywhere else such explanations on how to use Hopfield networks in learning and in a pseudo-code algorithm to use in a real task.

Advanced topics

Personally, I see the remaining chapters as advanced topics: Deep Boltzmann machines, variational encoders, GANs and introduction to reinforcement learning. Probably exception of deep backpropagation in Chapter 9. I would say what is now known as deep learning now was the inception of the architectures mentioned in sections 9.1 till 9.7.

Glossary, basic linear algebra and statistics

Appendices provide a fantastic conceptual introduction to jargon and basics to main mathematical techniques. Of course, this isn't a replacement to fully-fledged linear algebra and statistics book but it provides immediate concise explanations.

Not a cookbook: Not import tensorflow as tf book

One other crucial advantage of this book is that it is definitely not a cookbook. Unfortunately, almost all books related to deep learning are written in a cookbook style. This book is not. However, it is supplemented by full implementation in a repository supporting each chapter, URL here.

Conclusion

This little book archives so much with down to earth approach with introducing basic concepts with a respectful attitude, assuming the reader is very smart but inexperience in the field. If you are a beginner or even experienced research scientist this is a must-have book.  I still see this book as an academic book and can be used in upper-undergraduate class as the main book in an elective such as
"Mathematics of Deep Learning".

Enjoy reading and learning from this book. Thank you, Dr Stone, for your efforts on making academic books more accessible.

Disclosure: I received a review copy of the book but I have bought another copy for a family member. 

Saturday, 22 February 2020

A simple and interpretable performance measure for a binary classifier

Kindly reposted to KDnuggets by Gregory Piatetsky-Shapiro 

Preamble

The core application of machine learning models is a binary classification task. This appears in polyhedra of areas from medicine for diagnostic tests to credit risk decision making for consumers.  Techniques in building classifiers vary from simple decision trees to logistic regression and lately super cool deep learning models that leverage multilayered neural networks. However, they are mathematically different in construction and training methodology, when it comes to their performance measure, things get tricky. In this post, we propose a simple and interpretable performance measure for a binary classifier in practice. Some background in classification is assumed. 

Why ROC-AUC is not intepretable? 
PCC in Python (Author). 

De-facto standard in reporting classifier performance is to use Receiver Operating Characteristic (ROC) - Area Under Curve (AUC) measure. It originates from the 1940s during the development of Radar by the US Navy, in measuring the performance of detection.  There are at least 5 different definitions of what does ROC-AUC means and even if you have a PhD in Machine Learning, people have an excessively difficult time to explain what does AUC means as a performance measure. As AUC functionality is available in almost all libraries and it becomes almost like a religious ritual to report in Machine Learning papers as a classification performance. However, its interpretation is not easy, apart from its absurd comparison issues, see hmeasure.  
AUC measures the area under the True Positive Rate (TPR) curve as a function of the False Positive Rate (FPR) that are extracted from confusion matrices with different thresholds, $f(x)=y$ and  $\int_{0}^{1} f(x) dx = AUC$ whereby, y is TPR and x is FPR. Apart from a multitude of interpretations and easy to have confusions, there is no clear purpose of taking the integral over FPR. Obviously, we would like to have perfect classification by having FPR zero, but the area is not mathematically clear. Meaning that what is it as a mathematical object is not clear.

Probability of correct classification (PCC)

A simple and interpretable performance measure for a binary classifier would be great for both highly technical data scientist and non-technical stakeholders. The basic tenant in this direction is that the purpose of a classifier technology is the ability to differentiate two classes. This boils down to a probability value, Probability of correct classification (PCC). An obvious choice is so-called balanced accuracy (BA). This is usually recommended for unbalanced problems, even by SAS; though they used multiplication of probabilities. Here we will call BA as PCC and use addition instead, due to statistical dependence:
$PCC = \alpha TPR+ (1.0-\alpha TNR$

$TPR=TP/(ConditionPositive)=TP/(TP+FN)$
$TNR=TN/(ConditionNegative)=TN/(TN+FP)$
PCC tells us how good the classifier in detecting either of the class and it is a probability value, $[0,1]$. Note that, using total accuracy over both positive and negative cases are misleading, even if our training data is balanced in production, batches we measure the performance may not be balanced so accuracy alone is not a good measure. 

Attentive readers might note that this is about predictive values, Positive and Negative Predictive values, PPV and NPV match with the TPR and TNR respectively.

Production issues
Immediate question would be, how to choose the threshold in generating confusion matrix? One option would be to chose a threshold that maximizes PCC for production on the test set. To improve the estimation of PCC, resampling on the test set can be performed to get a good uncertainty.

Conclusion

We try to circumvent in reporting AUCs by introducing PCC, or balanced accuracy as a simple and interpretable performance measure for a binary classifier. This is easy to explain to a non-technical audience. An improved PCC, that takes into account better estimation properties can be introduced, but the main interpretation remains the same as probability of correct classification.  

Explore the notebook : pcc.ipynb


Please cite as follows:

 @misc{suezen20pcc, 
     title = {A simple and interpretable performance measure for a binary classifier}, 
     howpublished = {\url{https://memosisland.blogspot.com/2020/02/a-simple-and-interpretable-performance.html}, 
     author = {Mehmet Süzen},
     year = {2020}
}  

Friday, 27 September 2019

On modern data scientist: A blind empiricist is not a data scientist

As mentioned by Professor Pearl graciously on twitter 

Preamble
Hubble Space Telescope (Wikipedia)
Computational science is to
modern data scientist, as telescopes are
for astrophysics.

A better software developer than a statistician and better statistician than a software developer would have been a good definition for the early 2010s in identifying who would be a data scientist. In the late 2010s, trends changed dramatically, a data scientist is now identified as who can turn any set of data to run through machine learning libraries and getting a model to deploy for service.  Unfortunately, this blind empiricism is now considered as a data science practice in many industrial places and the term "scientist" lost its intellectual practice and turn into the mass hysteria of producing "junk science" blindly in the name of "democratisation of data science".

Who is the modern data scientist? 

Modern data science actually goes beyond statistics and machine learning. Modern data scientist practice computational science from dynamical systems to game theory or graph theory. One could think of such practice as applied mathematics or statistical physics as well.  For example, most of the neural networks is actually originating from statistical physics. In that sense, a modern data scientist is a computational scientist building mechanics of data.


  1. The exploratory analysis goes beyond basic PCA or clustering to be able to form causal relationships or establish mechanics of the data.
  2. Can express the mechanics of data in mathematical models and build parametric inference. Not all parameter estimations are learning.
  3. Use machine learning algorithms from libraries by knowing the underlying algorithm and can relate this to the mechanics of data.
  4. Build algorithms fusing above work.
  5. Explainable and transparent work.
  6. Document the findings as in the scientific paper and scientific software. 

Ignoring the above practice and treating data science similar to a web-based software development activity is not a fair practice and an immense waste of time. Organisations should understand that investing in data science means investing in the new computational science of building mechanics of data. Pushing the outcome of such a scientific practice to make a real-world impact lies in the novelty of scientist and as in any scientific funding, this is a very risky investment.

Misconception in democratisation of data science

The democratisation of data science does not mean that anyone should build learning or statistical models using machine learning libraries and put lots of data to get a black-box model as a blind empiricist. Democratisation was about the availability of tools and services at very low cost and open culture of transparency in algorithmic and software work.

Artificial Intelligence is modern data science

The separation of AI from the above definition of data science is not really clear. While AI combines the same characteristics to build so-called intelligent agents.

Conclusion

Having a perspective and understanding of what is modern data science about will help organisations better orient in building modern data science capabilities.

Postscript: Further reading and on the mechanics of data

We used a term the mechanics of data, it implies the effort to put in finding signatures of causal relationships and make sense of the correlations within the data. The reason is one of the core scientific methods that give rise to modern science lies in Newton-Leibniz mechanics. Coveney and his co-worker's deep dives in intricacies of practising science and data science.
  • Big data: the end of the scientific method?
    Sauro Succi and Peter V. Coveney
    [article]
  • Big data need big theory too
    Peter V. Coveney, Edward R. Dougherty and Roger R. Highfield
    [article]
Post-Postscript
Judea Pearl, a pioneering scientist on causal inference field, a quiet revolution in statistics and data science, Turing award laureate has similar critique on excessive empiricism. His post explains: 

Radical Empiricism and Machine Learning Research, which is also published as an article here: doi

Thursday, 10 January 2019

The fundamental problem of causal inference: causality resource list Looper

Preamble


One of the main tenants of practical data science is performing statistical inference on data sets which are assumed to be representations of populations of activity, natural or man-made. A specific case is called causal inference, which probably the core interest of decision makers and probably the main reason why businesses or industry funds data science projects in the first place. Either by trying to find a cause of an event or understand the impact of data science and AI products. A recent popular book of "Why" once again put causal inference into the major market [pearl2018]. However, the nightmare for a data scientist is that there is a fundamental limitation of performing such an inference. It stems from the fact that, the condition whereby to test causal link, i.e., establishing cause and effect, on a given data point cannot occur simultaneously. This is the so-called FPCI, the fundamental problem of causal inference [Holland86] and it can only be resolved approximately. This implies a data point cannot be both treated and not-treated simultaneously. For example, a patient cannot have a condition that receives treatment or no treatment at the same time, or a customer cannot be in the campaign or excluded at the same time. This post provides possible approaches in tackling it with pointers to resource and software tools.  The core problem is a missing data issue, but note that the missingness here originates from not a measurement error but fundamentally non-existing data point, so it is not only simple data imputation issue. More extensive resource list can be found, a resource list called looper is available on GitHub,  A resource list for causality in statistics, data science and physics. [looper]
Figure: Looper the movie revolves
around the causal loop (Wikimedia)

Rubin causal model: A-null test with the inherent contradiction


The question of why as in what is the cause of an event inherently a physics question and goes into space-time concept of general relativity and in classical mechanics in general. Popular time-travel movies, such as looper, see Figure, causality loops creates a curious non-intuitive phenomenon. From a data analysis perspective, the Rubin causal model [Rubin1974]  asserts that the causal effect can be quantified with A-Null test. What does this mean? Cause, i.e., treatment as a medical connotation, is the cause of the event, i.e., the effect or the outcome, can be quantified by the algebraic difference between the expected value of the outcome and it's counterfactual, a fancy name for what would have been the outcome in the absence of the treatment. Unfortunately, this is inherently contradictory as mentioned above, so-called FPCI, the fundamental problem of causal inference [Holland86]. On a single sample, i.e. event,  this A-null test cannot be applied because data is missing causally.  In estimating the A-null test, two groups are designed, so that they are drawn from the same population, recall the law of large numbers. One group receives the treatment and the other does not by design. Over time the effect of the treatment measured on both groups and Rubins A-Null test is applied. Not surprisingly they are called control and treatment groups and this procedure is called Average Treatment Effects (ATE). The mathematical exposure of this procedure is well established and can be found in standard texts, see Looper, but mathematically ATE reads  $\mathbb{E}(Y_{i} | T_{i} = 1) - \mathbb{E}(Y_{i} | T_{i} = 0) $.

Matching or balancing

Randomized control trails (RCT) constructs control and treatment groups. To compute ATE robustly, the statistical properties of covariates, set of features used in the study, from control and treatment must be similar. Any technique try to address the balancing issue is called matching [stuart2010].  Prominienet example in this direction is propensity score matching, using similarity distances between covariates, implemented in R via matching package based on genetic search. 

Imputation approach: Causal inference as missing data problem

One way to overcome FPCI is applying an imputation to missing data, predicting outcome value in case of control sample, vice versa. Using advanced imputation techniques one can resolve FPCI.  One prominent example is via Multiple Imputation, implemented in R mice package.

Summary

We have reviewed the fundamental problem of causal inference (FPCI) . For causality resources, a resource list called looper is available on GitHub,  A resource list for causality in statistics, data science and physics, please sent  a pull request for additions.Note that causality is a large research area from Bayesian Networks, Pearl's do calculus and uplift modelling.


References

[pearl2018] Judea Pearl and Dana Mackenzie, The Book of Why: The New Science of Cause and Effect,  Basic Books; 1 edition (May 15, 2018)
[Holland1986] Holland, Paul W. (1986). "Statistics and Causal Inference". J. Amer. Statist. Assoc. 81 (396): 945–960. 
[Rubin1974] Rubin DB (1974). “Estimating Causal Effects of Treatments in Randomized and Nonrandomized Studies.” Journal of Educational Psychology, 66, 688–701.
[stuart2010]  Elizabeth A. Stuart, Matching methods for causal inference: A review and a look forward Stat Sci. 2010 Feb 1; 25(1): 1–21.
[looper] A resource list for causality in statistics, data science and physics http:github.com/msuzen/looper.

Thursday, 3 January 2019

Core principles of sustainable data science, machine learning and AI product development: Research as a core driver

Kindly reposto to KDnuggets  by Gregory Piatetsky-Shapiro


Preamble 

Almost all businesses and industry embraced Machine learning (ML) technologies. Apart from ROI concerns, as it is an expensive endeavour to develop and deploy a service driven by ML techniques, sustainability as in going beyond proof-of-concept core development appears to be one of the roadblocks in data science. In this post, we will outline basic logical core principles that can help organisations for sustainable AI product development cycle, apart from reproducibility issues. The aim is giving a coarser view, rather than listing fine-grain good practice advice.

Research as a core driver: Research Environment

Regardless of the size of your organisation, if you are developing machine learning or AI products, the core asset you have is a research professional, data scientist or AI scientist, regardless of their academic background. Developing a model using software libraries blindly won't resolve issues you might encounter after deployment of the product. For example, even if you need to do a simple hyperparameter search, this can easily yield to research. Why? Because most probably no one ever tried building a model or try a modelling task using your dataset and you might need a different approach than ML libraries provide. A simplest different angle or deviation from ML libraries will yield to a research problem. 
  • No full 'black-box' approaches.
  • No blind usage of software libraries.
  • Awareness and skills in the mathematical and algorithmic aspect in detail.
Figure: A schematic of core principles for AI product development.
Separate out research code and production code

Software development is an integral part of ML product development. However, during research, a code development can go very wild and a scientist, even if they are very good software developers, would end up creating hard to follow and poor code. Once there is a confidence in reproducibility and robustness of results, the production code should be re-written with high-quality software engineering principles.

Data Standardisation: Release data-sets for research 

A cold start problem for ML products is to release and design data-sets before even doing any research like work. This, of course, has to be aligned with industrial requirements. Imagine datasets like MINST or imagenet for benchmarking. Released sets will be the first step for any model building or product development, and would constitute a data product themselves. Data versioning is also a must.

Do not obsess with workflows: All workflows are ad-hoc

There is no such thing as a universal or generic workflow. A workflow depends on a human understanding of processes and steps. Human understanding is based on language and linguistically there is no such thing as universal language, at least it isn't practical yet c.f., universal grammar. Loosely defined steps are sufficient for research steps. However, once it entered into production, then much more strict workflow design might be needed, but be aware all workflows are ad-hoc.

Do not run sprints for core data science 

Agile principles are suitable for software development innovations. Sprints or Agile is not suitable for AI research and research environment, it is a different kind of innovation than software engineering. Thinking that Agile is a cure to do scientific innovation is naive wishful thinking. Structuring a research group,  periodic reviews and releases of the results via presentations and detailed technical reports are much more suitable for data science on top of mini-workshops. A simple proposal runs can also be made to decide which direction to invest, akin to research proposals.

Feedback loop: Service to Business decision making back to research

A service using ML technologies should produce more data. The very first service monitoring is A/Null testing, meaning that what would happen in the absence of the AI product. Detailed analysis of the service data would bring more insights both for business and to research. 
  • produce impact assessment: A/null testing
  • quality of service: Quality of service can be measured basically on what is the success of the ML model, this has to be technical.

Conclusion and outlook

There is no such thing as free-lunch and developing AI products won't be fully automated soon. Tools may improve the productivity immensely but AI replacing a data scientist or AI scientist is far from reality, at least for now. If you are investing in AI products, basically you are investing in research at the core, missing that important point may cost organisations a lot. The basic core principles or variation of them may help in sustaining AI products longer and form your teams accordingly.
(c) Copyright 2008-2024 Mehmet Suzen (suzen at acm dot org)

Creative Commons License
This work is licensed under a Creative Commons Attribution 4.0 International License